Data Caching
Data caching improves performance by storing recently accessed data in memory for faster retrieval. Data caching happens in both TEs and SMs.
TEs manage SQL client connections and execute SQL queries against cached data. A cache hit occurs when the required data is available in the TE’s cache.
A cache miss occurs when the required data is not available in the TE’s cache. The connected TE is aware of other peers (TEs or SMs) that have the required data in their cache. The TE also determines which peers can provide the data in the shortest amount of time.
If the atom is not available in any other TE or SM cache, the TE sends a request to an SM to load the atom from disk. The SM loads the atom and sends it to the TE that requested the atom.
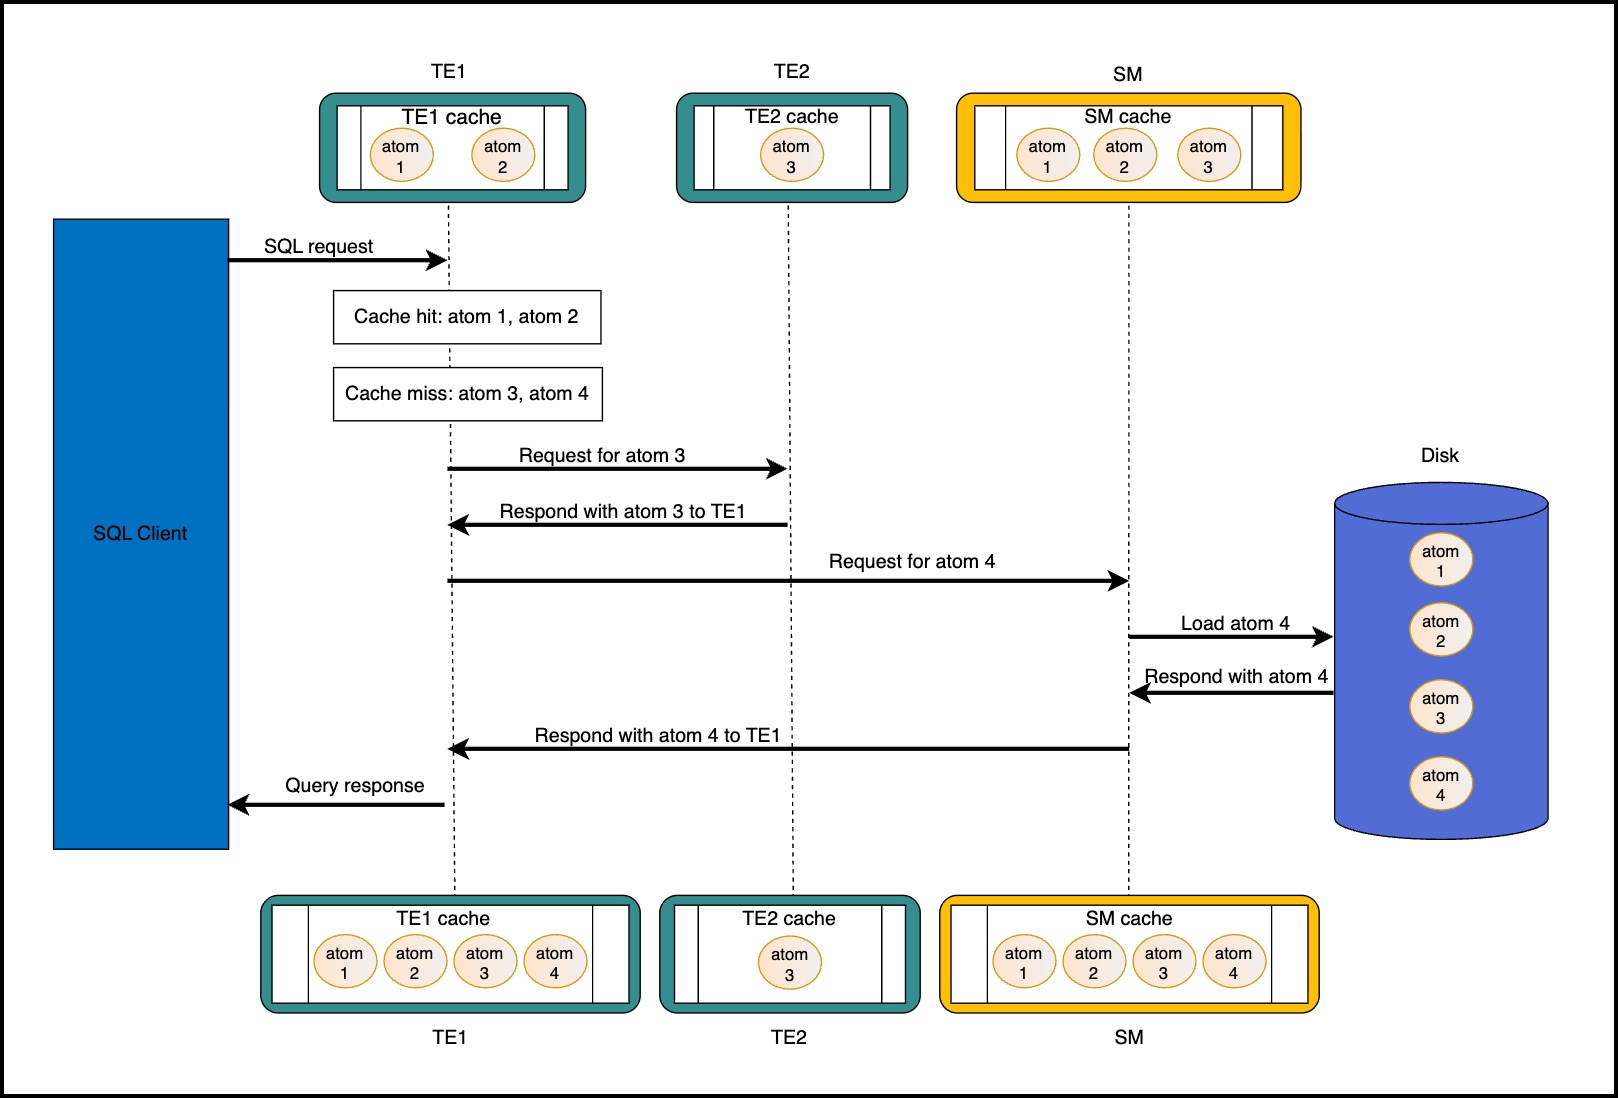
In the following example, a SQL client requests data from TE1, to which it is connected.
TE1 identifies the four atoms required to fulfill the request.
TE1 contains atom 1 and atom 2 in its cache.
TE1 is also aware that TE2 and SM have atom 3 in their cache.
TE1 tracks the response time of other database processes.
TE1 requests atom 3 from TE2 and retrieves it.
atom 4 is available only on the disk.
TE1 sends a request to SM for atom 4.
SM loads atom 4 from disk and sends it to TE1.
The SQL query can now access atom 1, atom 2, atom 3, and atom 4 from TE1.
Subsequent queries requesting the same data from TE1 can reuse the data cached on TE1 or SM, avoiding network and disk overhead. Fetching data from the TE1 cache avoids the overhead of fetching it from another process.
Cache Manager
The Cache Manager maintains references to all cached atoms. When the cache reaches its maximum capacity, the Cache Manager provides references to candidate atoms for eviction based on the configured cache replacement policy A garbage collector removes the atoms to free space in the cache.
There are two cache replacement policies:
-
[Default] Least Recently Used (LRU)
LRU tracks the recency at which the atoms are accessed. This policy assumes that an atom that has not been accessed recently is less likely to be accessed again and is considered for eviction. This policy is effective for simple workloads. LRU is prone to cache pollution caused by sequential scans because atoms accessed only once can evict frequently reused atoms from the cache. -
Low Inter Reference Recency Set (LIRS)
LIRS improves on LRU by considering recency and frequency at which the atoms are accessed. LIRS assumes that atoms with stronger reuse patterns are more likely to be accessed again. LIRS is useful for workloads with varying access patterns.Atoms are classified as
hotorcold. Frequently accessed atoms are tracked in ahotlist and infrequently accessed atoms are tracked in acoldlist. Each cached atom also tracks whether it is currently in thehotorcoldlist. The size of thehotlist is limited. By default, thehotlist is limited to 80% of the--memvalue assigned to a database process. When this limit is exceeded, atoms at the bottom of thehotlist are moved to thecoldlist.Use the
--cache-hot-percentoption to change the percentage of cache memory allocated tohotatoms. For more information, see Database Options.LIRS is scan-resistant, which prevents a large sequential scan from evicting frequently reused useful data from the cache.
To change the default cache replacement policy, use the --cache-manager option.
For more information, see Database Options.